Benchmarking
The Benchmark page has two jobs. One checks whether the model you configured is good enough for your telemetry. The other reproduces the research evaluation.
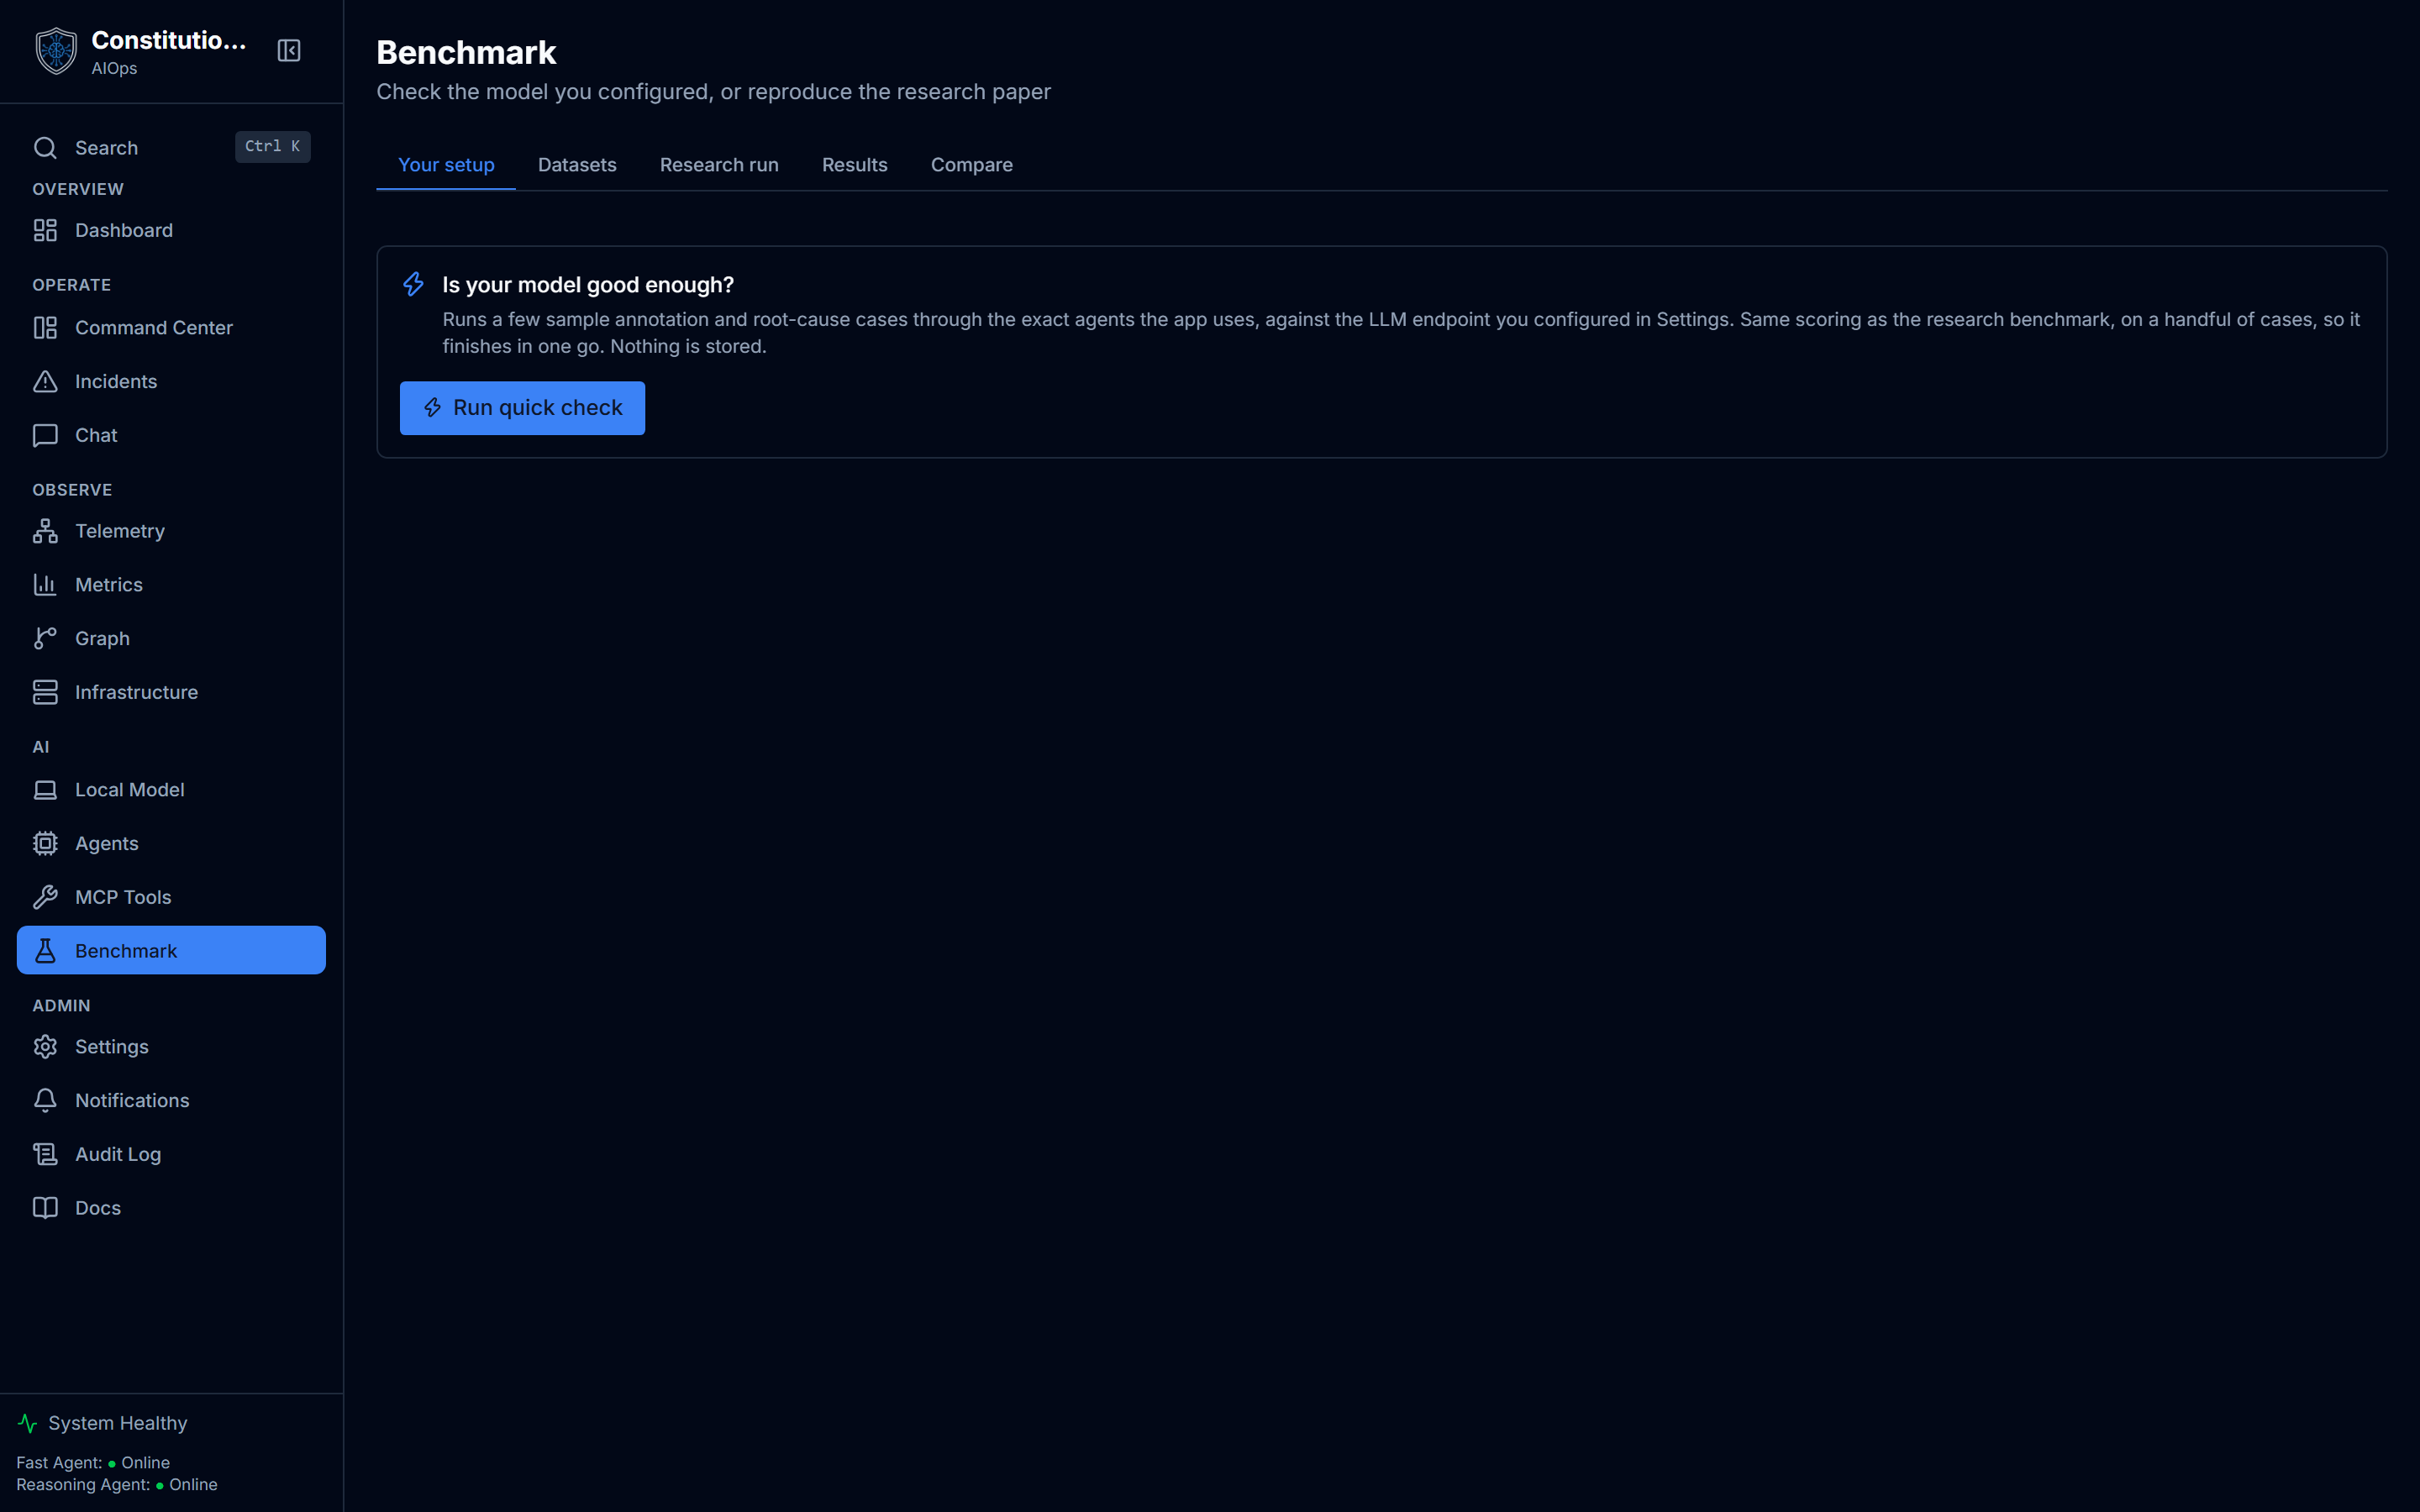
For the full tab-by-tab walkthrough, see Benchmark. For raw latency and determinism checks instead of accuracy scoring, see Metrics.
Your setup
The Your setup tab runs a few sample annotation and root cause cases through the exact agents the app uses, against the LLM endpoint you configured. It returns a pass rate, latency, and a per-case table, so you can decide whether to trust a given model before wiring it into production. This is the tab most self-hosters want.
Research run
The Research run tab reproduces the paper's evaluation over its datasets. It is meant for reproducing the published methodology, not for validating your own endpoint.
Datasets
The app ships a small synthetic sample so the page works out of the box. The research evaluation used the datasets below. Bring your own by replacing the files under data/benchmark/ in the same shape.
| Dataset | Source | Purpose |
|---|---|---|
| Annotation Test | Loghub HDFS + BGL | Log classification, normal versus anomaly |
| RCA Test | OpsEval | Root cause analysis questions |
Bring your own dataset
Replace the JSON files under data/benchmark/intermediate/datasets/ with your own cases in the same shape, then start a run from the Benchmark page. A configured LLM endpoint is required. You can regenerate the synthetic sample, or use it as a template, with:
python scripts/seed_benchmark_data.pyMetrics
- Annotation accuracy. Exact match on log classification.
- RCA accuracy. Partial match plus BERTScore F1.
- BERTScore. Semantic similarity of the answer to the reference.
- Latency. P50, P95, and P99, with network compensation.
About the research results
The published accuracy and latency results, the full methodology, and the comparison against other models live in the research paper, which is maintained separately from this repository. This page documents how to run the benchmark yourself, not the paper's numbers.